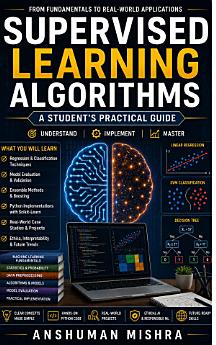
Supervised learning Algorithms A student’s practical guide
About this ebook
“Supervised Learning Algorithms: A Student’s Practical Guide” is designed to be a complete, student-friendly resource spanning from fundamentals to real-world applications. It blends solid theory, intuitive explanation, hands-on practice, and deep reflections on ethical and future directions in machine learning.
Why This Book Matters: Benefits of Study
1. Accurate, Reliable Predictions
Supervised learning trains models using labeled data, empowering them to make precise, dependable predictions once they’re well-trained .
2. Clarity and Interpretability
Many algorithms—like linear regression and decision trees—are transparent and easy to interpret. This clarity is especially vable in domains like education, healthcare, or finance, where understanding model decisions is critical ..
3. Wide-Ranging Applicability
From discovering spam emails to forecasting housing prices, supervised learning spans classification and regression tasks and touches nearly every industry—healthcare, finance, tech, agriculture, climate science, robotics, and more .
4. Practically Accessible for Students
Its structured nature—train on labeled data, test, iterate—makes supervised learning ideal for learners. Simple yet powerful, it’s accessible for beginners using intuitive models, and expandable toward advanced techniques like neural networks over time .
5. Enhances Critical Thinking and Creativity
Working with real-world datasets and building predictive models fosters analytical thinking and creativity—skills highly valued in academics and industry .
6. Automates and Scales Tasks
Supervised models can automate repetitive tasks—like grading assignments or detecting fraudulent transactions—freeing time and energy for more complex, human-driven work .
7. Supports Active and Adaptive Learning
Educational systems powered by supervised learning enable personalized instruction and adapt in real time—improving learning outcomes and engagement.
How This Book Facilitates Learning
Structured Learning Approach
· Clear progression from foundational math to advanced models, tuned with your preferred “Chapter-X / X.X” structure for clarity and easy navigation.
· Foundations (Chapters 1–2) ensure students build competency before diving deeper.
Balanced Theory and Practical Application
· Each concept is explained theoretically and reinforced with intuitive, accessible examples.
· Hands-on Python exercises using libraries like scikit-learn make learning practical and code-first.
Algorithmic Breadth
· Covers essential models: regression and classification basics, ensemble methods, boosting (XGBoost / LightGBM), and hyperparameter tuning.
· Encourages experimentation and a deep understanding of model behavior.
Model Evation and Best Practices
· Teaches rigorous evation using metrics (accuracy, precision, F1-score), validation strategies, ROC/AUC understanding, and discussions on overfitting vs. generalization.
· Also addresses ethical AI, model interpretability, and fairness concerns.
Case Studies and Real Projects
· In-depth projects: housing price prediction, spam filtering, churn analysis, handwriting recognition.
· Hands-on experience is supplemented with dataset access, real-world insights, and optional competitions or extension ideas.
Future-Focused Discussions
· Covers current trends and research, interpretability, ethical considerations, and explores how supervised learning fits into the evolving landscape of AI.
Supportive Resources
· Glossary of terms, appendices summarizing math foundations, references to advanced resources like online courses or research monographs.
· Clear guidance for independent exploration or deeper study.
Learning Outcomes: What Students Gain
By diving into this book, students will:
1. Master Supervised Learning Fundamentals
Gain strong conceptual understanding and practical competence.
2. Evate & Deploy Models Effectively
Understand how to build, validate, interpret, and deploy high-quality models.
3. Think Critically about AI Systems
Develop ethical awareness and critical reasoning regarding data bias and model behavior.
4. Communicate with Clarity
Learn to articulate model assumptions and decisions clearly to varied audiences.
5. Apply Skills Across Domains
Be ready to apply supervised learning in real projects—be it academic work, internships, or competitions.
Summary
“Supervised Learning Algorithms: A Student’s Practical Guide” is more than a textbook—it’s a learning journey:
· Accessible yet comprehensive: Starting from mathematical foundations, building up through advanced algorithms, with a balance of theory and hands-on practice.
· Relevant and modern: Covers real-world use cases and the ethical dimension of AI.
· Empowering: Equips students with skills to build, evate, and deploy intelligent systems that matter.
By working through this book, students will emerge not just with knowledge, but with confidence—ready to contribute to data-driven solutions in any domain they choose.
Chapter-1: Introduction to Supervised Learning
1.1 What is Machine Learning?
Machine learning (ML) is a subfield of artificial intelligence (AI) that focuses on the creation of algorithms and models that can learn from data and make predictions or decisions without being explicitly programmed for a specific task. Instead of writing a set of rigid instructions, a machine learning model is trained on a large dataset to identify patterns, relationships, and trends. The core idea is to allow the computer to "learn" from examples.
The process typically involves:
· Data Collection: Gathering relevant data, which can be in various forms like text, images, numbers, etc.
· Feature Engineering: Transforming raw data into a format that is suitable for the model to learn from. This often involves selecting and modifying the most important attributes, or "features," of the data.
· Model Trang: Using an algorithm to train a model on the prepared data. During this phase, the model adjusts its internal parameters to mmize prediction errors. This is the "learning" part.
· Model Evation: Testing the trained model on a new, unseen dataset to check its performance and accuracy.
· Deployment: Putting the trained model into a real-world application to make predictions on new data.
For example, imagine a spam filter for your email. Instead of a programmer writing a rule for every single spam word ("if email contains 'free prize,' mark as spam"), an ML model is trained on thousands of emails that have already been labeled as either spam or not spam. The model learns to identify patterns—like the frequency of certain words, the sender's address, or the subject line—that are common in spam emails. Once trained, it can then accurately classify a new, unseen email as spam or not.